new

Get trending papers in your email inbox!

Subscribe

Trending Papers

byAK and the research community

Trending Papers

TradingAgents: Multi-Agents LLM Financial Trading Framework

A multi-agent framework using large language models for stock trading simulates real-world trading firms, improving performance metrics like cumulative returns and Sharpe ratio.

  • 4 authors
· Dec 28, 2024
Submitted by
a43992899

YuE: Scaling Open Foundation Models for Long-Form Music Generation

YuE, a family of open foundation models based on LLaMA2, can generate long-form music with aligned lyrics, coherent structure, and appropriate accompaniment using innovative techniques in next-token prediction, conditioning, and pre-training.

  • 57 authors
· Mar 11, 2025
Submitted by
oriuta

Apodex 1.1: Scaling Agentic Intelligence for Complex Work

Apodex 1.1 improves sustained, verifiable progress on complex real-world tasks by scaling executable environments and training agents to coordinate long-horizon work with state maintenance and recovery.

apodex Apodex · Aug 24, 2026
Submitted by
andito

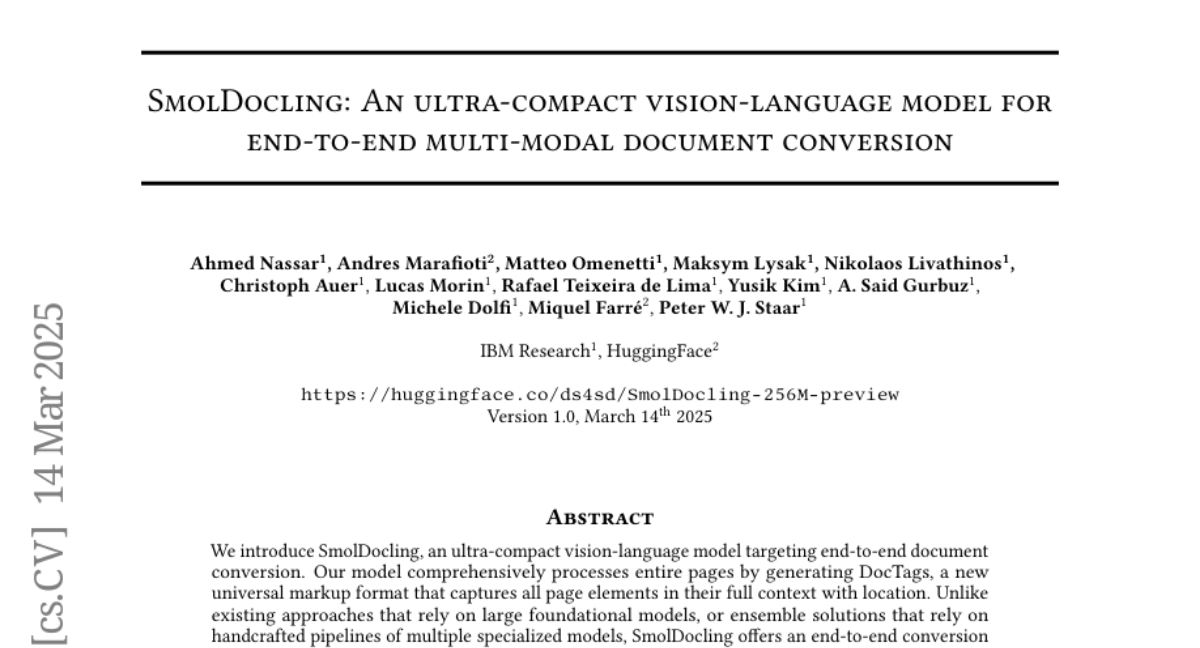
SmolDocling: An ultra-compact vision-language model for end-to-end multi-modal document conversion

SmolDocling is a compact vision-language model that performs end-to-end document conversion with robust performance across various document types using 256M parameters and a new markup format.

ibm-granite IBM Granite · Mar 14, 2025
Submitted by
TongZheng1999

Dream-RSI: Recursive Self-Improvement through Evolving Worlds

Dream-RSI enables scalable recursive self-improvement by using historical discovery replay to evaluate exploration policies offline, reducing costly online evaluations.

google Google · Sep 14, 2026

A decoder-only foundation model for time-series forecasting

A large language model adapted for time-series forecasting achieves near-optimal zero-shot performance on diverse datasets across different time scales and granularities.

  • 4 authors
· Oct 14, 2023
Submitted by
akhaliq

OpenDevin: An Open Platform for AI Software Developers as Generalist Agents

OpenDevin is a platform for developing AI agents that interact with the world by writing code, using command lines, and browsing the web, with support for multiple agents and evaluation benchmarks.

  • 24 authors
· Jul 23, 2024
Submitted by
taesiri

Paper2Agent: Reimagining Research Papers As Interactive and Reliable AI Agents

Paper2Agent converts research papers into interactive AI agents to facilitate knowledge dissemination and enable complex scientific queries through natural language.

  • 4 authors
· Sep 8, 2025
Submitted by
Sensen02

SoL-Pi: Recursively Scaling Auto-Research Loops for Efficient Agent Harness

As coding agents move from supervised code completion to unattended, around-the-clock exploration, their work expands from isolated predictions into long trajectories of reasoning, tool use, and feedback. Token efficiency therefore becomes important for scaling recursive self-improvement. We take an RSI-inspired approach at the harness layer, scaling auto-research loops across increasingly numerous and diverse environments for harness rollouts. At this scale, the process yields reusable improvements that transfer beyond their development setting, moving automated harness discovery toward production-level outcomes. Four mechanisms survive selection and form SoL-Pi, spanning action execution, context compaction, observation handling, and delegated reading. On the 51-task EdgeBench evaluation, SoL-Pi achieves performance comparable to Pi across GPT-5.6 Sol and Opus 5 while reducing recorded token traffic by 44.7-49.0% and API cost by about one third. In other words, estimated hourly savings are \8.75-13.50 relative to native Codex and Claude Code harnesses, and \4.36-5.71 relative to Pi.

nvidia NVIDIA · Sep 17, 2026

AutoDev: Automated AI-Driven Development

AutoDev is an AI-driven software development framework that automates complex engineering tasks within a secure Docker environment, achieving high performance in code and test generation.

  • 5 authors
· Mar 13, 2024
Submitted by
KYLN24

Atria Dawn: The Dawn of Agentic Superintelligence

Atria Dawn Preview is a foundation agentic language model trained through verified tool interactions that achieves strong benchmark results and demonstrates a shift toward human-AI project-level collaboration in scientific research.

internlm Intern Large Models · Sep 14, 2026

HuggingFace's Transformers: State-of-the-art Natural Language Processing

Transformers library provides state-of-the-art Transformer architectures and pretrained models for natural language processing tasks with a unified API and emphasis on extensibility and robust deployment.

huggingface Hugging Face · Oct 9, 2019
Submitted by
yshenaw

ZGCM-1: A Fully Open and Extremely Efficient Foundation Model for Math and Agentic Search

ZGCM-1 is a 7B open foundation model that combines internal reasoning with external tool use, trained via efficient architecture-system co-design, progressive long-context scaling, and autonomous agent workflows to achieve strong reasoning and efficiency.

zgcagi ZGCAGI · Sep 11, 2026
Submitted by
Shichengf

RSIAgent: Autonomous Exploration for Recursive Self-improvement in New Environments

RSIAgent is a training-free multi-agent framework that enables recursive self-improvement via autonomous memory construction and broad-then-deep exploration to adapt digital agents to new environments.

AetherLabs-AI AetherLabs-AI · Sep 14, 2026
Submitted by
bupalinyu

The Other Half of the Memory Wall: Serving 35B MoEs from SSD with Trained Routing Prediction

Mixture-of-experts (MoE) inference on consumer hardware is bounded by weight memory: a 35B-class model is 19.5GB at 4-bit, and sparsity shrinks the compute per token, not the bytes that must be held. Naive offloading to SSD does not help on its own, because layer N+1's experts must be chosen before layer N's output exists, so the reads cannot start early enough to hide behind compute. We present Edge0, a streaming MoE inference engine that closes the gap with a prerouter: a per-layer head predicts the next layer's routing one token ahead, and the prediction is consumed as the routing itself, so the staged expert set equals the routed set and nothing is dropped. An unmerged recovery LoRA, trained on the student path, pays back the quality lost to int4 quantization and routing replacement. On a single 24GB machine, Edge0 serves a 35B MoE at 20tok/s inside 3GiB of peak active memory, within a few points of its fp16 teacher on average across five public benchmarks. An 8B tier runs on the same framework, and the framework, checkpoints, and adapters are open source.

Edge0 Edge0 · Sep 16, 2026
Submitted by
andy-yang

FreeToken: Efficient Edge-Native MoE Serving with Bandwidth-Adaptive Execution

FreeToken is an edge-native Mixture-of-Experts serving system that dynamically maps computation and model state onto heterogeneous local hardware to run large open-weight models on personal machines.

Kronos: A Foundation Model for the Language of Financial Markets

Kronos, a specialized pre-training framework for financial K-line data, outperforms existing models in forecasting and synthetic data generation through a unique tokenizer and autoregressive pre-training on a large dataset.

  • 7 authors
· Aug 2, 2025
Submitted by
akhaliq

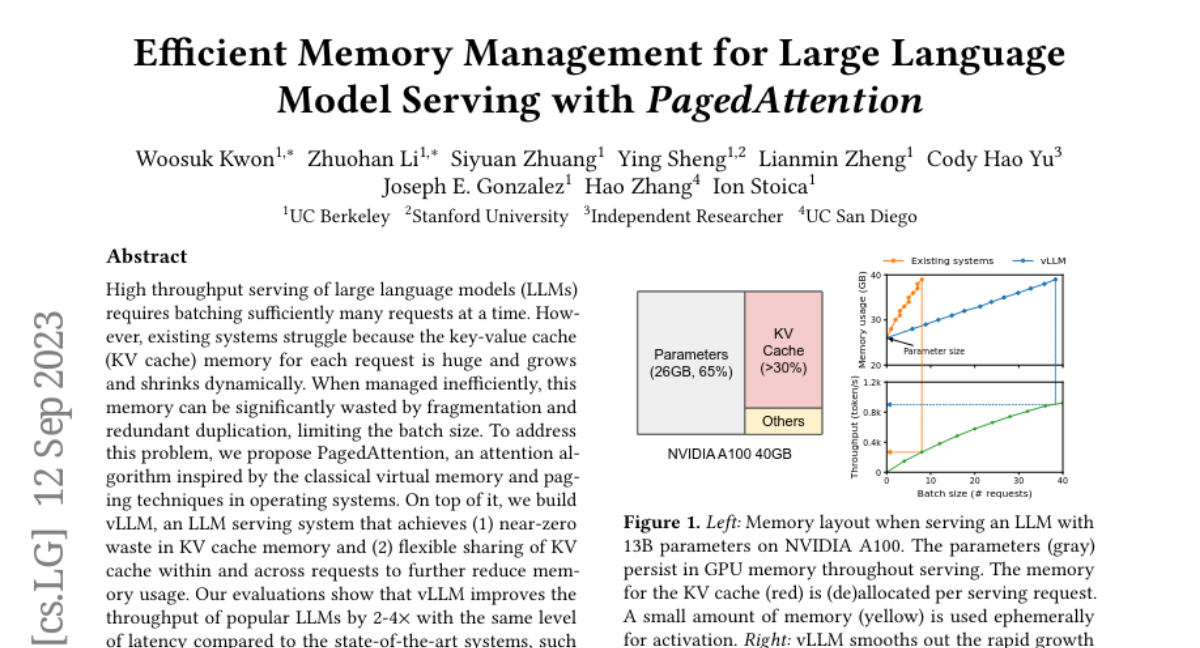
Efficient Memory Management for Large Language Model Serving with PagedAttention

PagedAttention algorithm and vLLM system enhance the throughput of large language models by efficiently managing memory and reducing waste in the key-value cache.

  • 9 authors
· Sep 12, 2023
Submitted by
Eureka-Leo

AI for Games in the Foundation Model Era

Foundation models, alongside advances in learned game-world models, are reshaping AI across the game lifecycle. Beyond playing games, recent systems model players and game dynamics, support design and development, adapt player-facing experiences at runtime, and evaluate resulting artifacts. Yet these directions have evolved largely separately, obscuring which capabilities transfer across settings and which remain tied to particular games, engines, interfaces, or player populations. We organize the literature into six roles according to the immediate use of AI output: playing and acting; modeling players and games; designing games; building and maintaining games; generating and adapting at runtime; and testing and evaluating games. For each role, we examine what structure is supplied by the game or workflow, what AI learns or produces, which capabilities and artifacts transfer across settings and roles, and what evidence supports the claims. We identify cross-role connections: trajectories train world models, learned environments provide experience for agents, design specifications drive executable implementations, and play or testing feedback guides revision. However, control schemes, rules, engine interfaces, state representations, and player contexts often remain setting-specific, so downstream claims require validation in the target setting. Evaluation is most standardized for bounded game playing and selected learned environments, while persistent state in learned worlds, repeated software revision, validated player modeling, sustained runtime adaptation, and representative automated testing remain less established. The central challenge is to reuse or transfer outputs and capabilities across roles while re-establishing evidence for effectiveness in the game-specific contexts where they are used.

Submitted by
akhaliq

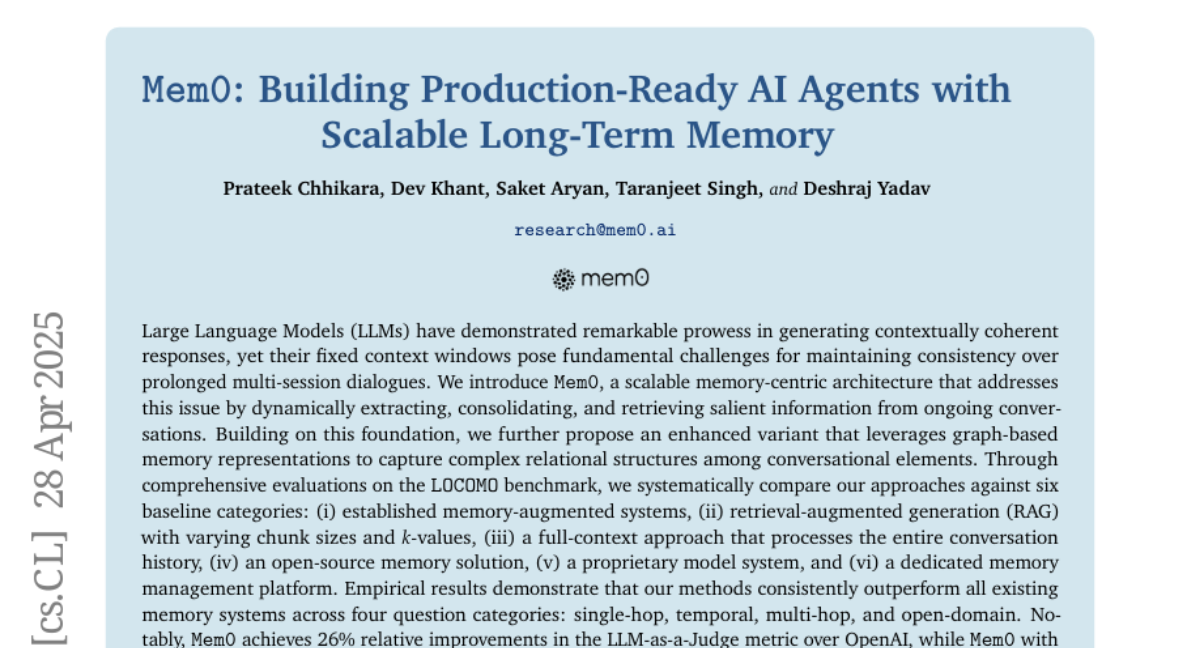
Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory

Mem0, a memory-centric architecture with graph-based memory, enhances long-term conversational coherence in LLMs by efficiently extracting, consolidating, and retrieving information, outperforming existing memory systems in terms of accuracy and computational efficiency.

  • 5 authors
· Apr 28, 2025
Submitted by
zhifeixie

VoiceMem: Streaming Dual-Brain Memory for Real-Time Interaction

VoiceMem introduces a dual-brain streaming memory architecture for speech language models that improves retrieval accuracy, emotional personalization, and real-time efficiency.

Submitted by
taesiri

MinerU2.5: A Decoupled Vision-Language Model for Efficient High-Resolution Document Parsing

MinerU2.5, a 1.2B-parameter document parsing vision-language model, achieves state-of-the-art recognition accuracy with computational efficiency through a coarse-to-fine parsing strategy.

  • 61 authors
· Sep 26, 2025
Submitted by
JarvisPei

NeoHorse-1: Towards Recursive Self-Improvement via Agentic Post-Training with Routing Harness

NeoHorse-1 uses agentic post-training with intelligent routing, structured feedback loops, and curriculum-based distillation to improve model capabilities across agent benchmarks.

TokenRhythm TokenRhythm · Sep 8, 2026
Submitted by
BoJack

AuK Technical Report: An Open-Source Foundational Model for Speech Generation and Editing

AuK is an open-source foundational model that unifies speech generation and editing via natural-language instructions and audio context, using a multimodal language model, joint VAE, hybrid rectified-flow Transformer, and efficient distillation for fast inference.

Tencent-Hunyuan Tencent Hunyuan · Sep 8, 2026
Submitted by
milkkarten

Prime Agent: A Self-Improving RLM Harness

Prime Agent is an open-source harness that uses recursive subagents, persistent computation, and agent-to-agent coordination to extend language models' long-horizon capabilities across coding and reasoning tasks.

PrimeIntellect Prime Intellect · Aug 24, 2026
Submitted by
akhaliq

Very Large-Scale Multi-Agent Simulation in AgentScope

Enhancements to the AgentScope platform improve scalability, efficiency, and ease of use for large-scale multi-agent simulations through distributed mechanisms, flexible environments, and user-friendly tools.

  • 8 authors
· Jul 25, 2024
Submitted by
taesiri

AgentScope 1.0: A Developer-Centric Framework for Building Agentic Applications

AgentScope enhances agentic applications by providing flexible tool-based interactions, unified interfaces, and advanced infrastructure based on the ReAct paradigm, supporting efficient and safe development and deployment.

  • 23 authors
· Aug 22, 2025
Submitted by
ChengCui

PaddleOCR-VL-1.6: Expanding the Frontier of Document Parsing with Under-Optimized Region Refinement and Progressive Post-Training

PaddleOCR-VL-1.6 enhances document parsing performance through targeted data optimization and progressive post-training techniques, achieving state-of-the-art results on OmniDocBench v1.6.

PaddlePaddle PaddlePaddle · Jun 2, 2026
Submitted by
taesiri

Unlimited OCR Works

Unlimited OCR introduces Reference Sliding Window Attention to eliminate growing memory consumption during long-sequence OCR tasks, enabling efficient transcription of multiple pages in a single forward pass.

baidu BAIDU · Jun 22, 2026
Submitted by
taesiri

LongCat-Video Technical Report

LongCat-Video, a 13.6B parameter video generation model based on the Diffusion Transformer framework, excels in efficient and high-quality long video generation across multiple tasks using unified architecture, coarse-to-fine generation, and block sparse attention.

meituan-longcat LongCat · Oct 25, 2025
Submitted by
RuofengYang

ARIS: Autonomous Research via Adversarial Multi-Agent Collaboration

ARIS is an open-source research harness that uses cross-model adversarial collaboration to ensure reliable long-term research outcomes through coordinated execution, orchestration, and assurance layers.

Submitted by
Longin-Yu

WeVisDoc: From Coverage to Capability for Robust End-to-End Document Parsing

Document parsing converts document images into structured content and requires reliable performance across diverse layouts and acquisition conditions. Yet training corpora are biased toward common document types and clean digital pages, while expanding coverage alone does not specify how to address a parser's remaining weaknesses. We present WeVisDoc, a two-stage data-centric framework for robust end-to-end document parsing. Stage I broadens semantic, structural, and appearance coverage through heterogeneous data and structure-preserving degradation synthesis. Stage II uses a held-out probe to measure the Stage I parser's residual errors within fixed visual-structural clusters. These diagnostics guide targeted data construction and reallocation of the target-token budget. WeVisDoc-4B achieves an Overall score of 95.38 on OmniDocBench v1.6 and a mean Overall score of 75.54 across the three PureDocBench tracks, ranking first among the compared end-to-end parsers in all four settings. Compared with Stage I, Stage II improves Overall scores for the 2B and 4B models on both benchmarks, with larger gains on the degraded PureDocBench tracks, including a 4.03-point gain for the 4B model on the Real Degraded track.

tencent Tencent · Sep 17, 2026
Submitted by
nielsr

RelateAnything: Real-Time Open-Vocabulary Relation Prediction From Any Inputs

RelateAnything is a lightweight open-vocabulary relation prediction model that accepts arbitrary predicate vocabularies and region sources at inference, trained on a large geometrically verified dataset with positive-unlabeled supervision and evaluated on a new cross-dataset benchmark.

  • 1 authors
· Sep 11, 2026
Submitted by
daixufang

Agent Lightning: Train ANY AI Agents with Reinforcement Learning

Agent Lightning is a flexible RL framework for training LLMs in various agents, using a hierarchical RL algorithm and decoupling execution from training to handle complex interactions.

  • 8 authors
· Aug 5, 2025
Submitted by
fuvty

Cache-to-Cache: Direct Semantic Communication Between Large Language Models

Cache-to-Cache (C2C) enables direct semantic communication between LLMs using neural network projections, improving accuracy and reducing latency compared to text-based communication.

nics-efc Tsinghua-NICS-EFC · Oct 3, 2025
Submitted by
Paranioar

SenseNova-U1: Unifying Multimodal Understanding and Generation with NEO-unify Architecture

Unified vision-language models treat understanding and generation as integrated processes rather than separate tasks, demonstrating strong performance across multiple multimodal capabilities including image synthesis and action reasoning.

sensenova SenseNova · May 12, 2026
Submitted by
stefan-it

GLiNER2: An Efficient Multi-Task Information Extraction System with Schema-Driven Interface

GLiNER2 is a unified transformer-based framework that supports multiple NLP tasks with improved efficiency and accessibility compared to large language models.

  • 5 authors
· Jul 24, 2025
Submitted by
taesiri

SkillOpt: Executive Strategy for Self-Evolving Agent Skills

SkillOpt introduces a systematic text-space optimizer for agent skills that trains skills as external agent state with stable updates and zero deployment inference overhead, achieving superior performance across multiple benchmarks and execution environments.

MicrosoftResearch Microsoft Research · May 22, 2026
Submitted by
jasonrqh

COLLEAGUE.SKILL: Automated AI Skill Generation via Expert Knowledge Distillation

Person-grounded AI skills are automatically distilled from heterogeneous traces into inspectable, correctable packages that capture both capabilities and behavioral patterns.

ShanghaiAiLab shanghai ailab · May 29, 2026
Submitted by
nielsr

Ultralytics YOLO26: Unified Real-Time End-to-End Vision Models

YOLO26 addresses real-time vision challenges through a unified model family with NMS-free inference, improved training strategies, and multi-task capabilities spanning detection, segmentation, and pose estimation.

Ultralytics Ultralytics · Jun 2, 2026
Submitted by
ZechenBai

Show-Harness: Just a VLM Agent Can Play Robots

Show-Harness links vision-language models to robot control via discrete semantic actions interpreted by embodiment-specific modules, enabling zero-shot and efficient fine-tuned deployment across robots and GUIs.

showlab Show Lab · Sep 9, 2026
Submitted by
toshas

Marigold V2: Revisiting Diffusion Transformers for Monocular Depth Estimation

Marigold V2 repurposes diffusion transformers for monocular depth estimation via single-step flow-matching inference, semantic alignment, and a Sinkhorn-based two-stage fine-tuning protocol, yielding sharper out-of-distribution depth maps and strong results on related dense regression tasks.

huawei-bayerlab HUAWEI Bayer Lab · Sep 8, 2026
Submitted by
stefan-it

GLiClass: Generalist Lightweight Model for Sequence Classification Tasks

GLiClass, an adaptation of GLiNER, achieves efficient and accurate sequence classification with zero-shot and few-shot capabilities, and PPO is adapted for multi-label text classification in data-sparse conditions.

Submitted by
xcjthu

MiniCPM4: Ultra-Efficient LLMs on End Devices

MiniCPM4, a highly efficient large language model for end-side devices, achieves superior performance using innovations in sparse attention, pre-training datasets, training algorithms, and inference systems.

openbmb OpenBMB · Jun 9, 2025
Submitted by
knightnemo

OpenWAM: An Open, Modular Exploration Towards Systematic World-Action Model Pretraining

OpenWAM factorizes world-action pretraining into modular components to identify key design principles, yielding a scalable open model with strong simulation and real-robot performance.

OpenWAM OpenWAM · Sep 7, 2026
Submitted by
jt-zhang

Vidu S2: Real-Time Interactive, Editable, and Spatial Video Generation

Vidu S2 introduces real-time interactive avatar and video editing models that support high-resolution spatial video generation and dynamic reference updates.

Tsinghua Tsinghua University · Sep 10, 2026

OmniFlatten: An End-to-end GPT Model for Seamless Voice Conversation

A novel GPT-based model, OmniFlatten, enables real-time natural full-duplex spoken dialogue through a multi-stage post-training technique that integrates speech and text without altering the original model's architecture.

  • 9 authors
· Oct 23, 2024

Editable Visual Design

A coding agent guided by a vision-language model generates editable layered designs by synthesizing isolated visual assets and iteratively refining native HTML/CSS layouts.

Tencent-Hunyuan Tencent Hunyuan · Sep 3, 2026
Submitted by
Zonghao2025

Securing the AI Agent: A Unified Framework for Multi-Layer Agent Red Teaming

AI-Infra-Guard is an open-source framework that addresses AI infrastructure security through layered detection paradigms spanning infrastructure, protocol, agent behavior, and model layers.

tencent Tencent · Jun 30, 2026
Submitted by
unilm

VibeVoice Technical Report

VibeVoice synthesizes long-form multi-speaker speech using next-token diffusion and a highly efficient continuous speech tokenizer, achieving superior performance and fidelity.

MicrosoftResearch Microsoft Research · Aug 26, 2025